Direct answersHow should you compare an ad network with a DSP?
Compare the buying role, source visibility, buyer controls and cost per accepted outcome; choose from documented settings and a controlled test, not labels.
Start with the job the account must perform. A provider may package publisher access, expose buyer-side bidding, or combine both. The useful comparison is the evidence you can retrieve after launch: which source served the impression, what the buyer could change, which event was billed and whether conversions were accepted after the agreed window.
Which conversion will you treat as accepted?
Write down the event that represents value for this offer, such as an approved lead rather than a raw form submission. Define the counting rule, attribution window, reversal conditions and source of truth before a campaign starts. Affiliate marketers should include advertiser approval status; ecommerce teams may need refunds or cancellations; app teams may wait for activation. If two platforms count different events, their CPA figures are not comparable even when the dashboards use the same label.
Who owns each step in the buying path?
List who selects or packages supply, evaluates bids, sets targeting, handles creative review, applies invalid-traffic filters, invoices spend and reports accepted conversions. OpenRTB describes standardized communication between buyers and sellers; the business relationship around that exchange can still vary. Ask the vendor to show the fields and report rows your account will actually expose. That role map reveals where an identifier disappears and who can correct a discrepancy.
How will you compare cost with campaign value?
Use impressions and clicks to diagnose delivery, then compare cost per qualified session or approved conversion after the event has matured. Effective CPC is spend divided by clicks; effective CPM is spend per thousand impressions. Cost per accepted outcome is spend plus material fees divided by accepted outcomes. Include operator time when one buying model needs substantially more manual work. Keep an acquisition target separate from billing: paying per click does not mean the platform optimizes or bills by CPA.
How can you make the comparison fair and reversible?
Keep the offer, landing page, conversion rule and measurement window stable across test cells. Limit differences to the buying model or a named setting, cap exposure, and record source, placement, geography, device and creative IDs. Before spend, set a loss ceiling and the evidence that would trigger a pause. A clean stop rule lets you test a new hypothesis without blending it into the history of the prior campaign.
| Buyer checkpoint | What to record | Why it changes the decision |
|---|
| Billable event, source, reporting owner and event definition. | The campaign event that created the charge, plus any platform fee or adjustment. | Prevents a CPC, CPM or CPA label from hiding different billing rules. |
| Offer, GEO, device, format, placement and destination. | Record the cohort keys available in both buying accounts and your analytics. | Lets you compare equivalent campaign traffic rather than blended account totals. |
| Qualified sessions, approved events, reversals and maturity date. | Use a named definition for each accepted event and note when it can be reversed. | Distinguishes fast reporting from a result that has completed review. |
| Media cost, material fees, accepted outcomes and operator time. | Calculate cost on the same accepted event and include fees that differ by model. | Shows whether the route fits the campaign's documented unit economics. |
| Targeting, bids, budget caps, exclusions and change history. | Capture which account role can edit the setting and whether it can be restored. | Makes it possible to explain and undo a material change. |
An eight-step test plan for performance buyers
- State the offer, accepted event, window and accountable decision owner.
- Confirm whether each dashboard counts clicks, impressions, raw conversions or approved outcomes.
- Record what each provider controls and which source identifiers appear after delivery.
- Test the destination and conversion path before relying on campaign totals.
- Keep the creative, audience context and measurement window stable across test cells.
- Reconcile platform reports with analytics and remove tracking faults before changing budget.
- Wait until the event can be approved or reversed, then judge a source using the mature outcome rather than a temporary count.
- Increase exposure only when the newest cohort meets the cost and quality rules you set before launch.
When should you pause or reset the test?
Pause the newest increment if spend cannot be reconciled, the landing path breaks, accepted events fall below the declared floor or a source concentration exceeds your cap. First check the tracker, redirect and attribution window; then restore the last stable settings and document the cause. Do not widen traffic to disguise a broken measurement path. Resume only when the corrected test can produce a result you can compare with the original cohort.
Which mistake most often invalidates a platform comparison?
The largest comparison error is changing several things at once: buying route, creative, audience, conversion event and attribution window. A resulting CPA difference cannot be assigned to a DSP or network if the cohorts are not equivalent. Keep a change log, preserve identifiers, and state the condition that would reverse your choice. The record matters as much as the first result because a later buyer must be able to reproduce the test.
What should you verify before relying on a platform claim?
This guide gives you a comparison method; it cannot promise a fixed traffic rate, a particular quality outcome, profit or organic visibility. Inventory, campaign eligibility, auction conditions and user response vary. Verify product features and billing in the current account, and use your own accepted conversion data to decide whether a source deserves more spend.
Read the IAB Tech Lab OpenRTB overview and IAB Tech Lab OpenRTB 2.6 specification for OpenRTB roles and request structure; the Google Ad Manager Programmatic Direct overview and Google Ads display media purchase options for Google-specific buying definitions; and the Google Ads CPM definition plus Google Ads average CPC definition for Google's CPM and average-CPC explanations. They support terminology, not FroggyAds billing terms. Confirm each platform's current event, fee, policy and attribution rules in the account you plan to use.
Which sellers and source IDs sit between you and an impression?
Draw the route from campaign setup to a user-visible ad: advertiser account, buyer-side platform, exchange or network relationship, seller or publisher and measurement system. Ask where the same source ID appears in each report. If a reseller, sub-network or placement group is hidden, note that limitation and keep the first test narrow. The comparison is not settled by the number of integrations; it depends on whether the account can expose the supply details required for your decision.
How do bidding software and packaged inventory differ in practice?
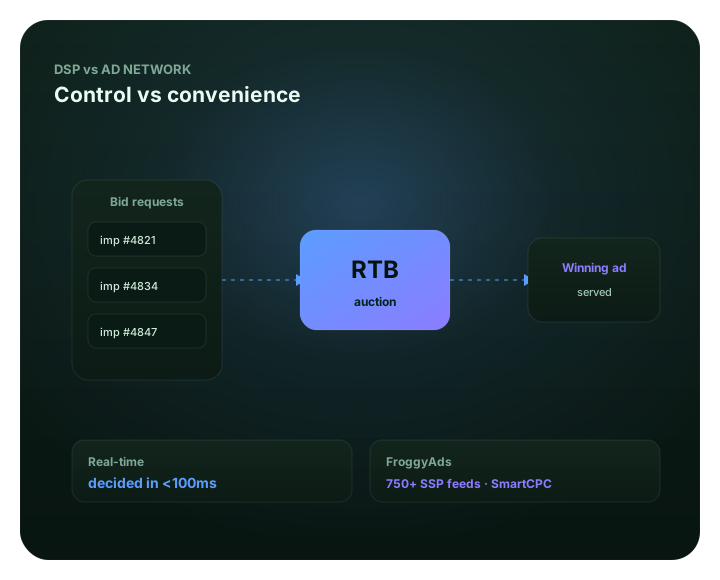
A DSP describes a buyer-side operating tool; an ad network describes a supply and commercial relationship. A network can add automated bidding, targeting and a self-serve interface, while a DSP can route demand through network or reseller supply. OpenRTB standardizes parts of programmatic communication, but it does not certify how a vendor invoices, filters traffic or reports conversions. Ask for an account walkthrough that follows one campaign event end to end.
Who can change bids, pacing, sources and creative?
For each material lever, record whether your operator can edit it, automation can override it or the provider's team controls it. A hands-on media buyer may value source exclusions and bid limits; an advertiser with one test may prefer fewer controls if the vendor explains how it optimizes. Ask whether excluded sources can re-enter automatically and whether settings are logged. The right amount of automation is the amount you can audit against campaign outcomes.
How do you compare the cost of a click, impression and approved outcome?
CPC and CPM show how media is bought or reported; they do not establish whether an offer generated value. Add platform, measurement or service costs that differ between providers, then divide the comparable cost by the same accepted outcome. For a lead-generation affiliate campaign, use approved leads after reversals. For an online store, decide whether refunds and margin change the value. State the window and denominator beside every rate.
What should you test first when comparing buying routes?
Begin with the offer's eligible audience and one conversion event. Then make two test plans that share a landing page, creative promise, geography and attribution window. For each route, record targeting fields, format availability, billing event, source detail and change controls before the first impression. If the provider cannot expose a necessary field, mark it unavailable instead of estimating it. A small, comparable test teaches more than a fast launch with different assumptions.
Keep UTM or other click identifiers consistent and verify that redirect parameters survive to the landing page. Compare platform clicks with analytics sessions, then inspect event timestamps and source IDs for the accepted conversion. Differences can reflect consent, redirect loss, event definitions or attribution windows. Write down the cause only when evidence supports it. If the discrepancy has no explanation, pause scale and ask each provider for the underlying report fields.
Once the agreed window has closed, compare supply detail, targeting controls, buyer workload, reporting delay, discrepancy resolution and accepted-outcome cost. Do not assume that the provider with the most rows in a report has better traffic; those rows are useful only if they map to decisions. Record which feature changed the result, which limitation remains and what evidence would change the selection.
Scale the winning route in steps that preserve source and test-cell visibility. Recheck the marginal cohort after each material budget or targeting change; a campaign average can hide weaker new delivery behind earlier conversions. If the next increment misses your cost ceiling, pause it and compare against the last stable configuration. This is a buyer-controlled decision process, not a promise that either buying model will produce a fixed outcome.
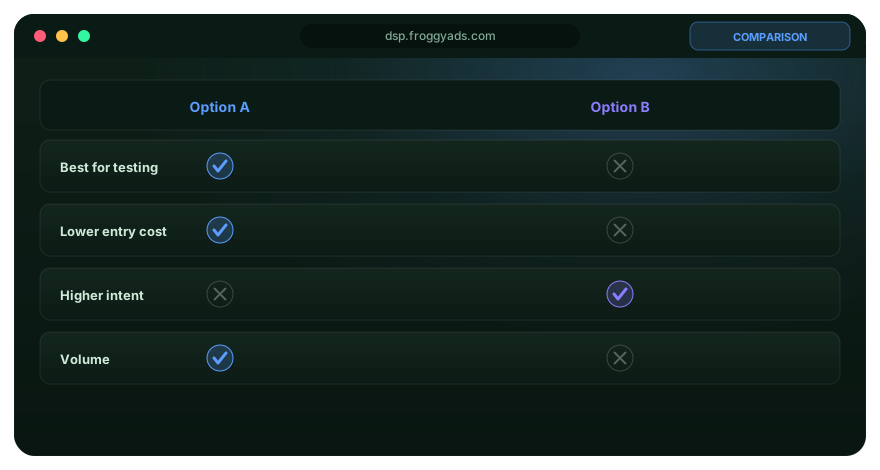
| Evaluation question | DSP evidence | Ad network evidence |
|---|
| Where does inventory originate? | SSP, exchange, deal and seller identifiers where available | Publisher, site, app, zone or managed supply description |
| Who changes delivery? | Buyer rules plus declared automation | Buyer settings plus network optimization |
| How is cost normalized? | Media and platform cost per accepted outcome | Media and service cost per accepted outcome |
| Can weak supply be removed? | Source, seller, placement, deal or domain controls | Publisher, source, zone or placement controls |
| What triggers rollback? | Marginal value, discrepancy or source concentration breach | The same declared business and quality thresholds |
Which advertiser situations change the buying-model decision?
An affiliate buyer needs the advertiser's offer rules in the comparison, not just the platform's targeting menu. Confirm eligible countries, device traffic, creative wording, redirect behavior and whether a conversion must be approved before it counts. Use source IDs to identify where an offer receives qualified visits, but do not scale on raw clicks when the affiliate program can reverse or reject conversions. FroggyAds is a practical option when the offer fits the available self-serve settings and you want to manage those tests yourself.
A professional media buyer usually needs repeatable cohort evidence. Split a test by a single meaningful variable, retain campaign and source names, and compare the newest spend with the original baseline. A DSP's source and budget levers are useful when the operator can review them each day. If those controls are not used or the event is unreliable, simplify the test before adding more targeting dimensions.
An agency should compare permission boundaries as well as media features. Keep each client's budget, creative approval, conversion ownership and source exclusions distinct, and decide who can change shared defaults. A self-serve account is valuable when buyers can work without mixing client evidence; a managed network relationship may fit a specialist placement that a client's policy already approves. Document the division so one client's optimization does not alter another's setup.
For an advertiser launching one market and one landing page, the decisive question may be setup friction: can the buyer select an eligible format, set a cap, verify the click path and review a source report without a separate integration project? A packaged network can be simpler, but confirm that it can still show enough evidence to stop a weak placement. FroggyAds suits a self-directed test when its current campaign settings match that brief.
For regulated or brand-sensitive offers, establish creative approval and placement policy before comparing price. Ask which site, app, category or source identifiers are visible and who applies an exclusion. Make the buyer's compliance rule part of campaign QA and save the approval record. If the reporting view cannot demonstrate that a required exclusion worked, do not infer compliance from the platform label or a broad inventory statement.
A conversion-focused campaign should judge the additional spend, not the platform's lifetime average. Keep an early cohort and the newest increment separate; allow the accepted event to mature; then compare approved value after material fees and reversals. If you switch route, keep the conversion definition and landing page fixed so the buyer can explain the difference. The best fit is the route whose controls and reporting match that decision.
What should you verify before funding a test?
Request a written list of eligible formats and markets, targeting fields, source identifiers, reporting latency, billing events, invalid-event treatment and conversion options. Ask which controls you can change yourself, what is automatic and whether exclusions are immediate. These questions turn a generic sales comparison into a setup checklist for your own offer. Use a real campaign example during onboarding so both sides agree on where a source ID and conversion appear.
Separate self-serve operations from assisted setup or managed optimization. Confirm who reviews a creative, who investigates a discrepancy, which report exports you can access and who owns policy decisions. For an agency, identify account permissions before inviting client users. A low advertised media rate is not a complete cost comparison when routine troubleshooting requires additional operator time or a separate service.
Before launch, learn how account balance, campaign history and downloadable reports are handled if you pause or close a test. Keep your own campaign IDs and conversion records so a later buying route can be compared against the same baseline. A documented exit process helps you stop a campaign cleanly; it does not depend on whether the provider calls itself a DSP or an ad network.
State the condition that would reverse the selection. A buyer might keep the DSP when source-level controls make a new market test diagnosable, but choose a packaged network for a specific relationship if its eligible supply and reporting meet the brief. This is a conditional decision tied to one offer, format and period, not a universal statement that one category always performs better.
Record the offer, campaign objective, market, device, format, source granularity, accepted event, attribution window and review date. Then the next media buyer can reproduce the same comparison instead of treating a prior platform choice as permanent. If any of those conditions changes, label the next test as a new decision rather than a continuation of the old result.
Name the person who will review the mature cohort, the date for that review and the pause rule. This keeps the decision accountable after launch.