Digital marketing, privacy, experimentation and measurement

A/B Testing: Experimental Design, Analysis and QA

By FroggyAds, the self-serve advertising platform. Updated: 2026-10-24.

A/B testing is a controlled experiment that randomly assigns eligible units to a control and one alternative so a predeclared outcome can be compared under the same measurement and maturity rules.

A/B testing
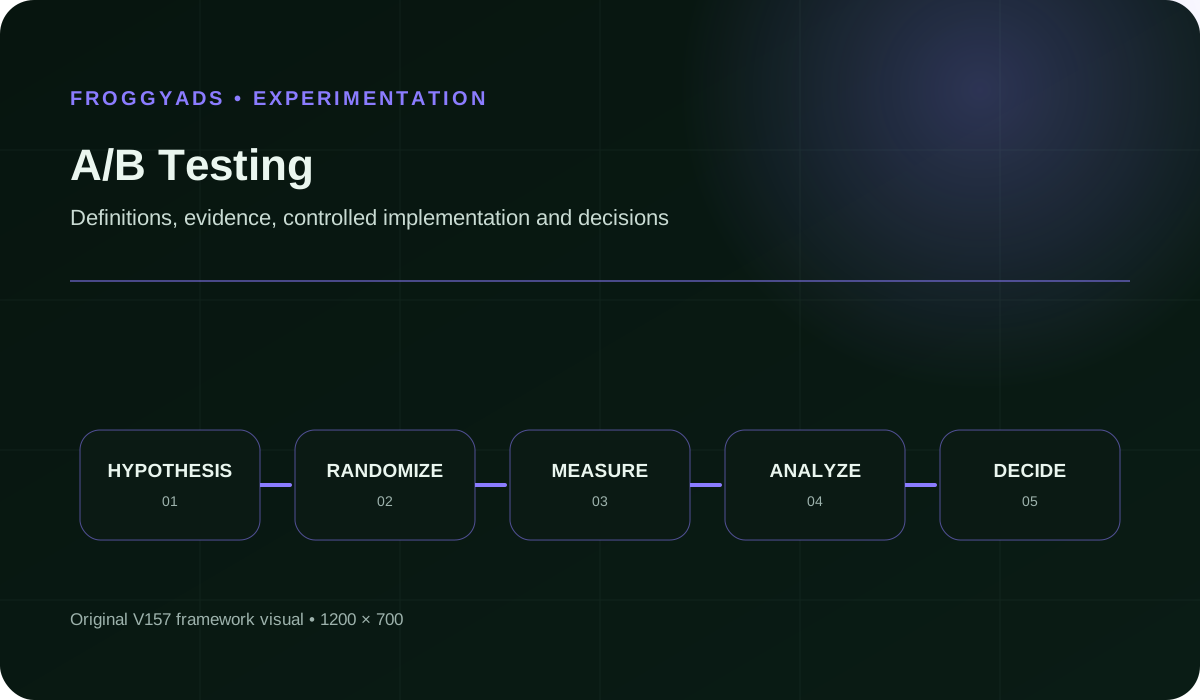
A/B Testing framework for planning, production, measurement and controlled improvement

Plan a useful experiment and its statistical method

Quick answer: Run an A/B test when you can assign eligible people fairly, deliver two defined experiences and measure a decision that matters. Choose the outcome and analysis plan before exposure begins. FroggyAds can support the traffic purchase through targeting, budgets and source controls; your experiment system must handle assignment, variant delivery and statistical analysis.

For experimental-design principles and statistical methods, consult the NIST Engineering Statistics Handbook. Choose the method around the question and data, rather than treating one result threshold as universal.

Five decisions to settle before buying test traffic

  • Choose the action the result will change: keep the current experience, replace it, or collect more evidence.
  • Define the eligible participant and assign that unit consistently; a returning visitor should not switch treatment accidentally.
  • Separate a delivery check from an outcome decision. Broken assignment needs attention before conversion-rate comparisons.
  • Choose the sample approach, outcome delay and stopping rule before inspecting which version appears ahead.
  • Plan a safe rollout and a reversible fallback. A useful experiment needs an operational decision at the end.

What does random assignment let you compare?

Random assignment supports a fair comparison between experiences; it does not remove measurement faults or uncertainty.

Assign each eligible participant at random to the control or alternative without using the outcome you hope to improve. It reduces systematic selection differences at assignment. It does not guarantee identical group counts, eliminate chance variation or repair a broken event pipeline. Those limitations belong in the interpretation of the result.

Define the unit before choosing the split. For a visitor-level test, repeated sessions from one person are not automatically independent participants. An account-level change may need assignment by account so colleagues share the same experience. Decide what identity your implementation can maintain, including what happens when people return or change devices.

A before-and-after comparison asks a different question. It may reflect a changed page, but also a different audience, season or offer. Two independently delivered campaigns can differ for similar reasons. Describe those comparisons honestly. If you need a controlled treatment effect, establish and verify the assignment process that supports that claim.

Assignment unit
The visitor, account or other entity allocated to a treatment; its identity determines which observations belong together.
Control
The reference experience against which the planned alternative is evaluated.
Percentage-point difference
The subtraction of one percentage rate from another; distinct from relative percentage change.
Stopping rule
The planned conditions under which outcome analysis ends or an intervention occurs.

Choose a feasible experiment around a meaningful customer change

Build the experiment around a choice you would otherwise make with weaker evidence. Perhaps you can explain the same offer in two credible ways, or simplify a form without changing qualification requirements. State what you will do if the alternative helps, harms or leaves too much uncertainty. This makes the cost of learning easier to justify.

Some changes should be repaired directly. A missing price, inaccessible error message or broken checkout does not need a contest against the defect. Validate the repair, then consider experimentation where two acceptable experiences remain. Keeping a known failure online merely to call it a control can waste visitors and undermine trust.

Choose a question your traffic and operating cycle can answer. A business with rare purchases may learn about technical feasibility before it can estimate a small sales effect precisely. Resist replacing the real outcome with an easy click simply to finish sooner. Use the click as a diagnostic and keep the commercial uncertainty visible.

Ready for paid acquisition

Bring suitable visitors to a ready experiment

Bring a defined paid-acquisition audience to your experiment with FroggyAds and control the purchase through campaign settings. We let you select available targeting, bids, budgets and sources. Connect that campaign to a validated experiment destination, and keep the traffic configuration stable enough to interpret what the page treatment changes.

Create My Free Account
Illustration of audience targeting controls for a a/b testing test

Eight parts of an interpretable experiment

#Experiment componentWhat to specify before exposure
1Decision and hypothesisName the proposed change, why it could affect the customer and what result would justify replacing the control.
2Eligible populationSpecify who can enter, when eligibility is checked and how staff, repeat visitors and earlier treatment exposure are handled.
3Control and alternativeSave the exact versions and intended difference. Keep the offer, measurement and unrelated journey behavior consistent.
4Assignment unitChoose visitor, account or another suitable unit, then verify the configured split and assignment persistence.
5Exposure recordRecord which experience was actually delivered. Assignment alone does not prove the page rendered or its event arrived.
6Primary outcomeDefine one main decision measure with qualification, duplicate and timing rules. Retain diagnostic and customer-protection measures separately.
7Sample and maturityPlan observation needs and calendar coverage, including enough follow-up for the outcome to be confirmed.
8Analysis and rolloutChoose the analysis and stopping approach in advance. State how uncertainty, practical value and harms affect the release decision.

Treat this table as a launch conversation between the marketer, experiment implementer and person validating outcomes. Each should be able to explain their part without guessing what another system means. If assignment is defined in one place and eligibility in another, compare the actual records before the test reaches customers.

  1. Choose the commercial decision and a treatment that could change it.
  2. Define eligibility, assignment and the outcome analysis before launch.
  3. Validate both experiences and trace assignment through to accepted outcomes.
  4. Monitor delivery and customer harm while respecting the observation plan.
  5. Assess integrity, effect, uncertainty and guardrails together before rollout.

How to run the test from question to a documented choice

1. Choose the decision you need to make

Write the action that follows the result. For example, you may need to decide whether an earlier explanation of delivery terms should replace the current checkout introduction. Specify the people affected and the cost of a wrong choice. A vague wish to improve engagement gives the analysis too many possible endings.

2. Explain why the proposed change should affect orders

Describe the mechanism behind the change. Earlier delivery information might help suitable buyers continue with fewer surprises, while discouraging people the offer cannot serve. That suggests looking beyond clicks to confirmed orders and cancellations. The hypothesis should make sense before any result arrives; it should not be a story assembled around the winning number.

3. Choose participant eligibility before observing outcomes

Choose eligibility using information available before the treatment can affect it. Document treatment of returning visitors and internal tests. Do not later remove people because they bounced, failed to submit or produced an inconvenient result. Those behaviors may be part of the treatment effect you were trying to understand.

4. Save the control and alternative versions

Keep a saved control and a versioned alternative. Review text, price, destinations and completion states on both. If you intend to test one explanation, avoid adding an unrelated discount only to the alternative. A combined change is possible, but the result then belongs to that bundle rather than to one sentence.

5. Verify allocation before reading outcomes

Confirm the assignment unit, intended ratio and behavior on a return visit. Compare actual group counts with the planned allocation using a suitable imbalance check. An imperfect split can arise by chance; a material unexplained mismatch needs investigation. Inspect eligibility, redirects and event collection before crediting either experience with a conversion advantage.

6. Check the full measurement route

Trace test participants from assignment through exposure to the recorded outcome. Check missing identifiers, duplicate events and differences between variant implementations. Your analyst must know whether the report counts assigned participants, recorded exposures or sessions. A treatment that breaks logging can appear to improve a rate simply by removing unsuccessful observations.

7. Freeze the decision and analysis rules

Record the primary measure, supporting diagnostics, unacceptable harms and the chosen statistical method. Define the meaningful effect you are trying to detect and the observation plan it requires. If the tool supports sequential inference, understand its rules; otherwise do not assume repeated checking leaves a fixed-horizon analysis unchanged.

8. Monitor safety while outcomes mature

Watch for delivery failures and customer harm throughout the run. Keep those operational checks separate from opportunistically declaring a winner. Respect the planned analysis approach and allow pending customer actions to mature. If a serious defect requires stopping, record the reason and limits of the evidence instead of presenting the interrupted run as a clean victory.

9. Read effect, uncertainty and tradeoffs together

Start with data integrity, then inspect the primary outcome and its uncertainty under the planned method. Consider whether the change is large enough to matter after implementation and operating costs. Review guardrails as well. A higher submission rate can be unattractive if it creates more invalid requests or reduces the value of accepted customers.

10. Choose rollout, rejection or an inconclusive result

Choose among rollout, rejection and an inconclusive decision. For rollout, confirm the exact tested version, support capacity and rollback route. Watch later performance as exposure expands because a larger audience may behave differently. For an inconclusive result, preserve the uncertainty and decide whether a better question is worth another investment.

Keep traffic comparable

Keep the media purchase aligned with the experiment

Use the FroggyAds format that fits the arrival experience: Push, Native, Display or Pop where appropriate for your offer. Keep format changes out of a page-only comparison. If you want to compare formats themselves, make that a separate buying decision with its own delivery assumptions and outcome measurement.

Create My Free Account
Illustration comparing advertising formats for a/b testing execution

Report primary outcomes, participants and customer guardrails

Report the primary outcome as the difference between control and alternative on the basis fixed in your analysis plan. Keep exposure health and customer guardrails alongside it. This prevents a precise-looking percentage from hiding missing participants, delayed outcomes or a commercially poor tradeoff.

MeasureDefinition to useWhen to inspect it
Accepted outcome rateQualified outcomes divided by eligible assigned units under the analysis plan. Show both group counts and rates; identify any different denominator explicitly.At the planned analysis point after required outcome follow-up.
Allocation integrityObserved assigned or exposed group counts compared with the configured ratio. State which counts the check uses and investigate unexplained mismatches.During launch checks and monitoring, before interpreting treatment effects.
Outcome maturityThe extent to which each cohort has completed the agreed observation window and qualification process.Before each authorized result review; show pending outcomes separately.
Absolute and relative effectReport percentage-point change alongside relative change. A move from 2% to 2.2% is 0.2 percentage points and 10% relative.With uncertainty at the prespecified decision point, not as a stand-alone headline.
Customer and business guardrailsMeasures that could make a nominal win unacceptable, such as invalid leads, cancellations, errors or workload. Define tolerated harm before launch.Continuously for serious harm; together with the final commercial assessment.
Version fidelityWhether the intended treatment, destinations and event definitions remained the ones actually delivered throughout the comparison.After deployment and every relevant release; annotate deviations immediately.

Reconcile the experiment report with the business system that accepts a lead or order. Avoid joining only successfully converted records and losing the rest of the assigned population. Keep missing data explicit. A technically valid calculation cannot answer the original question if its input population silently changed during processing.

Three experiments with different decision boundaries

A landing-page explanation

You want to know whether explaining a delivery condition sooner improves confirmed orders. Assign eligible arrivals to the current page or the revised explanation. Keep the condition itself unchanged. Record the version with the order so later cancellations can be compared with the original assignment, rather than only with the last page visited.

This answers a treatment question among the eligible arrivals in the experiment. It does not establish that paid traffic caused all subsequent sales, or that the same effect will hold for every source. A campaign holdout and a page-version test address different decisions. Name the claim you can support before expanding it.

Compare advertising creatives under actual delivery conditions

A creative comparison can be useful, but equal budgets do not prove random assignment. Auction conditions, optimization and available audiences can make two campaigns reach different people. Use an appropriately configured experimentation system when a causal message comparison is required. Otherwise treat the delivery results as buying evidence with those limits and inspect source and device mix.

Use heatmaps to propose a testable page change

Heatmap patterns can suggest that visitors miss an explanation or mistake a visual for a button. Inspect the page directly and propose a specific change. Then evaluate the change with an appropriate experiment if uncertainty remains. Microsoft Clarity describes heatmaps as aggregated interaction views; the pattern alone does not establish a treatment effect.

Five reasons to distrust an apparent winner

Stopping when the chart looks favorable

Repeatedly checking an ordinary fixed-horizon test and stopping at the first favorable threshold can distort its error control. Follow the planned stopping approach or use a method designed for sequential decisions. You can still stop a broken or harmful experience; label that action as a safety decision and explain what the interrupted data can support.

An unexplained participant imbalance

Unexpected allocation can reveal assignment, redirect, logging or processing problems. Do not repair the displayed ratio by deleting convenient records. Find where the discrepancy enters and whether treatment exposure affects inclusion. A valid imbalance check considers sample size as well as the ratio; visual inspection of percentages alone is insufficient.

Choosing the best of many convenient results

Trying many outcomes, variants and audience slices creates more opportunities for a chance finding. Select the main question beforehand and use an analysis appropriate to the planned comparisons. Treat interesting unplanned segments as hypotheses for follow-up. Reporting only the successful slice hides how many opportunities there were to find it.

Changing measurement during the run

A new event definition, consent implementation or order-status rule can change what the report counts. Check whether both variants were affected in the same way and at the same time. Preserve the original record and annotate the change. If comparability cannot be restored, restart a clearly identified experiment instead of combining incompatible data.

Scaling a result beyond its evidence

An experiment among one eligible audience does not automatically settle every market or device. Check who was represented, what offer was shown and how mature the outcomes were. Rollout can reveal operating constraints absent from the test. Keep customer-protection measures active and retain the tested control until the wider release is dependable.

These checks help you protect the purchase decision, not merely the appearance of a positive result. An experiment that rules out a risky change can save future spend. An inconclusive experiment can still reveal that assignment or outcome collection needs work. State that learning directly rather than giving every run a winning label.

Fund a validated route

Buy traffic after the test route is validated

We recommend confirming assignment and measurement before increasing paid exposure. With FroggyAds, you can set an affordable campaign budget and review source-level delivery while your experiment collects outcomes. Keep the campaign history with the test record so the team can distinguish a treatment change from a buying change.

Create My Free Account
Illustration of a campaign launch checklist for a/b testing

How much traffic and time should you budget?

Plan traffic from the outcome rate, meaningful effect and analysis method. No fixed visitor count settles every experiment.

There is no universal visitor count or duration that makes every A/B test conclusive. Planning depends on the baseline outcome rate, the smallest useful change, the statistical method and the uncertainty you can accept. Include outcome delay and calendar coverage as well. A rare purchase generally creates a different planning problem from a frequent page action.

Use a sample-size approach suitable for the outcome and assignment unit. Document its assumptions before funding the traffic. If the required exposure is beyond your budget, consider a larger meaningful change, a narrower decision or preliminary usability work. Buying more visitors without a feasible analysis plan can turn a small uncertainty into a large bill.

Budget for implementation, review and follow-up as well as media. Someone must investigate missing events, validate customer outcomes and support the selected experience. Set a spending boundary that the business can afford even if no winner emerges. FroggyAds campaign budgets help contain the acquisition spend; they do not replace your experiment planning.

Where does FroggyAds fit in an A/B testing setup?

Choose FroggyAds self-serve advertising for your test's paid-traffic input. We help advertisers and media buyers select supported formats, targeting, bids, budgets and sources. Keep those settings aligned with your acquisition brief. Your website or experimentation service distributes eligible arrivals between experiences and retains assignment, so you can separate the media purchase from the treatment comparison.

Connect the reporting layers deliberately. Available source identifiers and tracking macros can help your tracker connect delivery to later activity, while supported postbacks can report conversion events. Keep the experiment assignment in your own measurement route. Do not assume a campaign identifier by itself tells you which page version a returning visitor received.

Choose us when you want practical control over the media inputs to a test. You can refine an acquisition setup after its evidence is ready, then run the next comparison with a documented starting point. We do not promise that buying traffic produces a winner; the advantage is being able to fund, inspect and adjust the purchase.

What should the experiment tool be able to show?

  • How is the participant identified, and what happens to assignment when someone returns, signs in or changes devices?
  • Does the tool record allocation separately from the measured outcome, so missing conversions do not hide missing participants?
  • Which analysis and stopping method does the report use, and how does it handle multiple variants or metrics?
  • Can the team inspect the exact treatment, event definitions and changes that were active during each part of the run?
  • How quickly can you stop a harmful variant and restore the reviewed control without losing the experiment record?

Ask these questions against your actual setup. A landing-page editor, product feature system and advertising-platform experiment can operate at different units and expose different controls. Google Ads, for example, documents its own campaign experiment settings. Those settings are Google product capabilities, not evidence of identical experiment features in FroggyAds.

How to write a result the next buyer can use

Begin with the decision, population and tested difference. Show participant and accepted-outcome counts before presenting a percentage. State the analysis method, the observation window and any deviations. Give the effect with appropriate uncertainty, then explain whether it is useful enough to change the business decision.

Separate the observation from the recommendation. A small positive estimate may remain too uncertain to justify rollout. A technically persuasive increase may still fail a customer guardrail. If you recommend another test, specify what it would resolve and why the extra cost is justified. Keep exploratory findings clearly identified.

Close the record with the exact version selected, the rollout conditions and a person responsible for follow-up. Make the rejected or inconclusive version findable as well. That history prevents a team from repeatedly buying traffic to answer a question it already investigated, or accidentally reintroducing a change that failed for a known reason.

Frequently asked questions

When is A/B testing the right way to answer a question?

Use an A/B test when two controlled experiences can be assigned fairly, enough eligible observations can accrue, and a decision metric is defined in advance. It is a poor fit for one-off events, tiny samples, or changes whose effects cannot be separated from simultaneous business shifts.

How should a first A/B test be planned?

State the decision, hypothesis, eligible audience, control, single meaningful change, primary metric, guardrails, sample approach, duration, and stopping rule before exposure begins. Confirm the team can deliver variants consistently and record assignment independently of the outcome.

What resources belong in an experiment budget?

Allow for research, design, engineering, quality assurance, analytics, review, monitoring, customer support, and the opportunity cost of showing a weaker variant. Set a risk limit around the expected decision value instead of assuming experimentation is free because media spend is unchanged.

How should participants be defined for an A/B test?

Choose eligibility from the decision population, assign units consistently, and document exclusions before looking at outcomes. Returning users, accounts, devices, staff, and previous exposure need clear treatment so contamination does not turn a precise-looking result into an unreliable comparison.

What keeps the control and variant comparison fair?

Hold audience eligibility, timing, delivery quality, destination function, and measurement constant while changing the intended element. Monitor actual exposure and sample balance, since a perfect design specification cannot rescue a test when users receive the wrong experience or events go missing.

Which checks are required before an experiment starts?

Test both variants across supported devices, confirm assignment persistence, validate events and consent, inspect performance, rehearse rollback, and review customer-facing claims. Run an internal or limited exposure phase so obvious defects do not become part of the measured treatment effect.

How should A/B test results be interpreted?

Read the preselected primary metric with its uncertainty, sample quality, guardrails, exposure integrity, and practical effect size. A threshold crossing is not enough by itself; the team needs evidence that the observed change matters commercially and is not driven by instrumentation or repeated peeking.

What should be checked when an A/B result looks surprising?

Audit assignment, exposure, event definitions, missing data, sample balance, device and source mixes, concurrent releases, and the analysis window. Recalculate from raw records where possible before inventing a customer story to explain a result that may come from broken experimental plumbing.

Which practices make an A/B test untrustworthy?

Avoid changing metrics after seeing results, stopping opportunistically, excluding inconvenient observations, running conflicting treatments, or reporting only favourable segments. Preserve the plan, code, exposure data, analysis, and deviations so another reviewer can understand exactly what happened.

When should a winning A/B variant be rolled out?

Release more widely after the effect is practically useful, guardrails remain acceptable, the experience works technically, and follow-up capacity is ready. Increase exposure in steps, keep a rollback path, and compare later real-world performance with the experimental expectation.
Primary references and their scope

The NIST handbook provides experimental-design and statistical context. Google documents experiments within Google Ads; Microsoft documents its Clarity interaction views. Those tools have their own capabilities and requirements. The accessibility, privacy and content references below support implementation review rather than certifying this page or any proposed experiment as compliant.

A practical experiment brief you can complete

Use the prompts below to create a short working brief. Each answer should constrain a real decision rather than add paperwork. For the first run, choose a change your team can deliver and measure correctly. Keep a separate log for deviations so the original plan remains visible when you review the result.

The choice and the customer explanation

Write one sentence describing the change and one describing the expected response. For example, an earlier delivery explanation may reduce unsuitable orders while helping suitable customers commit. Decide whether the business would prefer fewer but more reliable orders. This keeps a raw conversion increase from becoming the default definition of success.

Record the current experience as the control, with a recoverable version and review date. Identify the decision-maker who will choose rollout, rejection or further work. The brief should make those options legitimate before anyone sees which treatment is ahead.

The participant and entry point

Describe the point at which someone becomes eligible and is assigned. Include the supported devices and any necessary market restriction. Write down how repeat visits and prior exposure are handled. If account members can influence one another, discuss whether individual visitor assignment would create contamination before choosing the implementation.

The treatment difference

List what changes and what stays stable: explanation, price, form, destination and fulfillment terms. Attach the reviewed versions. If the alternative deliberately combines several changes, say so. The experiment may estimate the bundle effect, but it will not tell you which individual edit deserves credit.

The allocation check

Name the system that assigns participants and the planned proportion per group. Explain how the team will verify persistence and detect allocation problems. Keep a small internal verification phase separate from the outcome analysis. Do not count staff test submissions as customer responses simply because they entered the same event stream.

The exposure and outcome join

Specify how assignment reaches the exposure record and how later customer actions link back to it. Test missing, duplicate and delayed records. Document what happens when an identity cannot be joined. This is particularly important when an order is confirmed in a different system or a lead receives its acceptance status later.

The main measure and guardrails

Write the primary measure in ordinary language, followed by its denominator and timing rule. Then name the customer or business harms that could prevent rollout. For a lead form, accepted leads may be more useful than submissions, with duplicate requests and sales workload as supporting checks. Choose measures that the business can actually validate.

The observation and stopping plan

Record the sample-planning assumptions, follow-up window and analysis method. Identify the safety conditions that require intervention regardless of the headline outcome. If funding expires before the planned evidence arrives, allow an inconclusive decision. Do not silently weaken the stopping rule because the campaign has reached its spending limit.

The release and follow-up decision

State what would justify adopting the alternative and what would keep the control in place. Include rollout capacity, known limitations and the fallback version. After release, inspect whether the wider audience and operating conditions remain consistent with the test. Keep that follow-up separate from rewriting the original experiment result.

Start with a traffic plan your experiment can explain

Create your FroggyAds account when the audience, destination and measurement route are ready. We provide the campaign controls to purchase relevant traffic within your budget. Start with a manageable setup, retain its source context and let the planned experiment analysis guide the next change.

Create My Free Account
Interpret the result

What does a reported lift actually mean?

A percentage-point change and a relative increase describe the same observation on different scales. Both need the underlying counts and a clearly defined population. Neither, by itself, establishes that chance variation, measurement loss or selection effects have been ruled out. Treat the arithmetic as the start of interpretation.

Read the comparison in order: Check who was assigned, whether the intended experience was delivered, which outcomes matured and how the estimate was calculated. Only then decide whether the difference is practically useful. This order prevents an attractive headline from distracting the team from a broken comparison.

Before adopting the alternative: Confirm the uncertainty under the chosen method, the customer guardrails and the tested version. Explain any departure from the original plan. If those conditions do not support a decision, retain the control and identify the specific gap a further investigation would need to close.

Decision gateQuestion to answerEvidence to retain
PopulationDid eligible participants enter the planned groups without treatment-dependent exclusions?Assignment counts, eligibility rules and the outcome of the allocation-integrity investigation.
OutcomeDo the accepted-action counts represent the same follow-up window and qualification rules?Group denominators, mature outcomes, missing-record handling and the agreed analysis method.
ActionDoes the effect and its uncertainty justify rollout without unacceptable customer or operating harm?The actual effect estimate, guardrail findings, selected version and reversible rollout decision.

Worked example: 0.2 percentage points is not 10 points

Hypothetical example: Control A has 200 accepted purchases among 10,000 eligible assigned visitors; alternative B has 220 among 10,000. The observed rates are 2% and 2.2%. B is ahead by 0.2 percentage points, or 10% relative to A: (2.2% minus 2%) divided by 2%. These counts alone are not a significance test or a FroggyAds result.

Choose FroggyAds for the acquisition side of your test

Use our targeting, budget and source controls to buy the audience your experiment is ready to receive. Preserve the assignment and outcome analysis in your experiment system, then use what you learn to plan the next purchase. Create your free FroggyAds account

Direct answer

A useful experiment ends with an honest decision

An A/B test is useful when a fair comparison helps you choose what to do next. Keep the control when the alternative disappoints, release it when the evidence supports the change, and acknowledge uncertainty when it remains. FroggyAds helps you manage the paid traffic that supports that learning.