Replace Social Media Marketing Hacks With Controlled Experiments
Treat every social media marketing hack as an unproven campaign hypothesis. Name the mechanism, protect the audience, cap exposure and keep one stable control so the result can support a real advertising decision. Preserve the campaign, source, creative and destination versions, then reconcile delivery with an accepted backend outcome after the same maturity window. That evidence tells you whether to scale, repair or stop without pretending that attention alone proves business value.
Choose a truthful campaign tactic with a clear limit
We recommend testing a social media tactic when you can explain the customer problem, the change you intend to make and the business action it should improve. This guide helps advertisers, affiliates and agencies make that decision without relying on a shortcut label. Choose FroggyAds for the paid-traffic stage when your message and destination are ready: our campaign budgets and source reporting let you inspect a separate acquisition test.
The boundary is firm: do not use deception, fabricated proof, unauthorized outreach, hidden automation, fake engagement or moving success criteria. A tactic that depends on those conditions cannot become a durable acquisition system. Replace the shortcut label with a clear hypothesis, document what would disprove it and stop when the agreed financial, audience or trust limit is reached.
Turn the tactic into a cause-and-effect mechanism
Write the tactic as a cause-and-effect statement. Identify the audience state, creative or offer change, expected behavior, accepted business event and evidence window. For example, replace use curiosity with a precise claim such as a problem-led native headline will increase qualified product-page visits for this audience without increasing rejection or complaint rates. That statement can be challenged and measured.
Reject ideas that cannot produce a negative result. Preserve the existing campaign cell, destination and conversion definition, then change the one element under review. Record who owns the test, the maximum spend, the audience ceiling and the rollback release. A named mechanism gives your team something to improve; a catchy hack name encourages repetition without learning. Add a short mechanism map that links the message, expected interpretation, next action and accepted event. Ask a reviewer to identify an alternative explanation before launch. If the test cannot distinguish that explanation from the proposed mechanism, narrow the audience or improve the measurement plan first.
Check the user experience and adverse signals
Review the experience from the user's side before launch. Check whether the message is clear about the offer, uses consented contact paths, avoids manipulative urgency and gives people a reasonable way to decline or leave. Confirm that the destination matches the creative promise and that a short-term interaction is not purchased by confusing the visitor about price, availability or intent.
Define adverse signals for the exact tactic: complaints, negative comments, blocks, opt-outs, rejected conversions, policy warnings or unusually weak downstream quality. Assign an owner and an early review point. When a tactic harms trust, pause it before the budget ceiling; the absence of a financial loss does not make audience harm acceptable. Review accessibility in the delivered format as well as the landing page. Text that is readable in a design file can fail at placement size, and motion, contrast or ambiguous controls can change who understands the message and who is excluded from the test.
How do you verify every claim in a social campaign?
Create a claim register for the creative, caption, landing page and follow-up. Link each factual statement, comparison, scarcity message and testimonial to an approved source and permitted use. Distinguish a documented product fact from a campaign hypothesis. If evidence is missing or outdated, remove or narrow the statement before buying traffic.
Keep the claim version connected to the creative and destination release. Reviewers should be able to see what was approved, who approved it and which campaign used it. This prevents a successful delivery result from being misread as proof that an unsupported statement was true. Recheck dynamic content, countdowns and price or availability statements at the moment of launch. If the page can change independently from the ad, create a release checkpoint that confirms the promise still matches what the visitor can actually obtain.
| Claim checkpoint | Evidence to retain | Release decision |
|---|---|---|
| Product or service fact | Current primary source, owner and review date | Publish only within the documented scope |
| Comparison or superiority statement | Comparable basis, current data and named limitation | Remove when the comparison cannot be reproduced |
| Urgency or availability | Real condition, duration and inventory owner | Stop when the condition is no longer true |
Which platform and advertising rules need review?
Check the current rules for the social platform, ad format, audience, market, claim category, automation method and landing experience. A tactic allowed in an organic post may be unsuitable for paid distribution, and a method acceptable in one market may require different consent or disclosure elsewhere. Keep the dated primary source beside the release record.
Do not design a test around evasion. Hidden redirects, disguised destinations, unauthorized scraping, misleading interface patterns and fake accounts create a different risk from ordinary creative experimentation. If eligibility is unclear, hold the tactic and obtain an accountable review instead of treating a successful publish attempt as approval. Keep the rule source, access date and decision owner in the campaign record. Platform interfaces and enforcement can change, so an old screenshot or another advertiser's experience is weaker evidence than current primary documentation for the same format and market.
Why does every hack test need a stable control?
A control preserves the current approved campaign, creative or workflow while the new mechanism changes one material variable. Keep audience eligibility, offer, destination version, accepted event, attribution settings and maturity window fixed unless one of those is the stated test. Without that reference, a result may reflect seasonal demand, a new source, a tracking change or a different offer.
Choose the comparison before launch and keep both cells identifiable. Do not move low-quality outcomes between cohorts or merge sources until the decision is complete. If delivery differs materially, report the imbalance and narrow the conclusion. A useful experiment reduces uncertainty; it does not force a winner from incomparable evidence. Record the date range, budget allocation, audience overlap and any frequency difference. When the control cannot receive comparable delivery, use the result as directional evidence and run a corrected follow-up instead of presenting a precise lift percentage.
Write spending limits and a stop rule
Write four limits: media spend, audience reach or contact count, elapsed time and a trust or quality threshold. Use the smallest exposure capable of answering the decision. Assign the account owner who can pause the campaign and make sure they can see the relevant source, rejection and complaint evidence while delivery is active.
A stop rule protects both economics and learning. Continuing after the planned ceiling can turn a bounded test into an uncontrolled campaign and encourage the team to change the success criterion. Pause at the limit, wait for the accepted outcome window and document the decision before funding another iteration. Distinguish a delivery problem from a negative business result. A technical defect may justify a repaired rerun, while a valid test that misses the accepted threshold should retire or materially change the hypothesis. Do not spend again merely to seek a more attractive chart.
| Exposure boundary | Evidence to watch | Required response |
|---|---|---|
| Budget ceiling | Spend by campaign and source | Pause at the written maximum |
| Audience ceiling | Eligible reach, frequency and exclusions | Stop when exposure exceeds the approved scope |
| Trust or quality signal | Complaints, rejections and adverse feedback | Escalate early; do not wait for full spend |
Judge accepted outcomes and campaign source records
Define an accepted outcome that reflects the business job: a qualified lead, verified signup, activation, order, subscription or another backend event. State exclusions, rejection reasons, attribution rule and maturity window. Clicks, views and engagement are useful diagnostics, but they do not prove that the tactic created valuable demand.
Join the campaign, source, creative, destination and backend outcome through durable identifiers. Report accepted and rejected events, operating workload and adverse signals beside spend. When the join is incomplete, label the gap and avoid a confident scale decision. FroggyAds can expose campaign and source activity; your advertiser-side system remains the authority for accepted value. Review cohorts after the same maturity period and keep cancellations, duplicates, fraud decisions or sales disqualifications visible. Otherwise a source with faster reporting may appear stronger simply because slower but valid outcomes have not had time to mature.
Compare the workload with the accepted outcome
Measure the time required to create, approve, moderate, respond, reconcile and document the tactic. Include specialist review, customer support and cleanup after a failed experiment. A manual engagement method can appear inexpensive when the dashboard ignores the people needed to sustain it, and a high response count may simply move work into another team.
Compare the workload with the accepted outcome, not with raw interaction. If the mechanism produces valuable results but cannot operate at the intended volume, test a narrower audience or redesign the workflow. Do not automate a weak process merely to preserve the label of a hack; automation can scale errors and policy exposure as quickly as it scales delivery. Include the cost of moderation during evenings or peak periods, delayed sales follow-up and exceptions that require a senior reviewer. A tactic is operationally viable only when the team can meet its response commitment without weakening other customer or campaign work.
Prepare a FroggyAds campaign and review source delivery
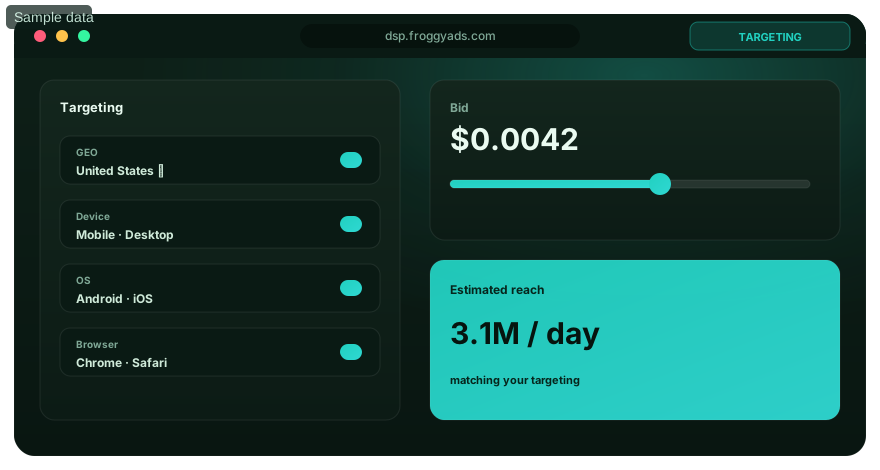
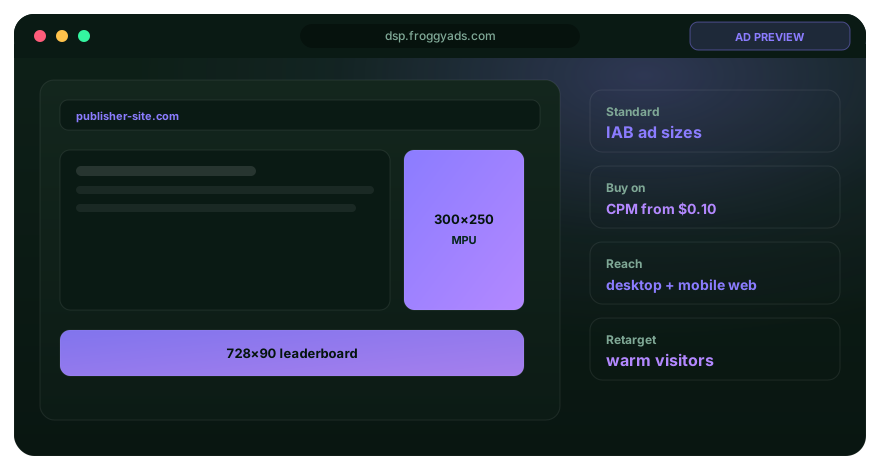
Choose FroggyAds for a separate paid acquisition test of the message you have prepared. Our self-serve workflow supports format selection, targeting, spending controls and source reporting. Start with an appropriate Push, Native, Display or Pop campaign, and keep its campaign identity distinct from your social-platform activity. These controls help you inspect delivery and adjust a specific source or setup condition when your customer evidence supports the change.
Start with a small eligible cell and inspect technical delivery before reading business performance. Wait for the declared outcome window, reconcile sources with accepted backend events and change one material variable in the next iteration. We provide the self-serve controls for execution; you remain responsible for claim support, consent, offer fit and the final scale decision. Use a campaign naming rule that includes the hypothesis and release version. That small discipline lets media buyers, analysts and account owners discuss the same evidence and avoids scaling a creative that was later corrected or withdrawn.
| Campaign checkpoint | Evidence to retain | Account action |
|---|---|---|
| Launch readiness | Approved creative, destination, audience and event | Fund only the bounded cell |
| Source evaluation | Spend, delivery, accepted and rejected outcomes | Keep sources separate until reconciled |
| Next iteration | Learning memo, limitation and new hypothesis | Scale, repair or stop from mature evidence |
Which adverse signals should you inspect first?
Monitor policy warnings, rejection, complaints, negative feedback, blocks, opt-outs, weak accepted quality, suspicious concentration and unexpected support demand. Compare these signals by campaign, source, creative and audience cohort. A blended average can hide a harmful cell whose engagement looks strong.
Write alert owners and response thresholds before launch. Some conditions require an immediate stop, while others justify a narrower diagnostic test. Preserve the exact creative and destination when investigating so the team does not overwrite the evidence. Resume only after the failed control has been corrected and the new acceptance rule is documented. Compare adverse signals with the relevant delivery denominator and audience context. One complaint may be material in a small sensitive cohort, while a raw count across unequal sources can mislead. Keep severity and recurrence beside the rate rather than reducing trust risk to one average.
Record the hypothesis, limitations and next action
Record the hypothesis, eligible audience, mechanism, control, variable, creative and destination releases, spend and exposure, accepted and rejected outcomes, adverse signals, operating effort, limitations and decision. Include the evidence window and anything that changed during delivery. This makes a failed test useful because it prevents the same unsupported idea from returning under a new name.
Choose one next action: scale within the verified boundary, repair a named control, run a narrower retest or stop. Do not convert an inconclusive result into a broad best practice. Link the memo to the campaign and source records so a later operator can reproduce the conclusion and see where it does not apply. Add the unanswered question and the evidence that would resolve it. This prevents a low-information test from being repeated unchanged and helps the team prioritize experiments that can remove the largest uncertainty from the campaign plan.
Maintain the process and review new cohorts
Promote a tactic only after the mechanism works across the documented conditions, adverse signals remain within the approved boundary and the operating effort is sustainable. Give it a descriptive process name, owner, version, source evidence, eligibility rule, monitoring plan and review date. Remove claims that extend beyond the tested audience or offer.
Retiring the shortcut label improves governance. Teams can review a process such as problem-led native creative for returning visitors more clearly than hack number twelve. Continue to compare new cohorts and reopen the decision when platform rules, audience behavior, offer economics or tracking changes. Archive the failed versions as well as the winner. They show which boundaries have already been tested and keep a new team member from reviving a discarded shortcut without understanding its rejected outcomes, audience impact or operational cost.
| Operational record | Evidence to retain | Maintenance rule |
|---|---|---|
| Validated mechanism | Repeated accepted-outcome evidence and limitations | Use only inside the tested boundary |
| Operating playbook | Owner, steps, approvals, stop conditions and rollback | Train users and version material changes |
| Scheduled review | Newest cohort, policy source and workload | Repair or retire when the evidence no longer passes |
Questions advertisers ask about social media marketing hacks
What makes a social media marketing hack useful?
A useful hack names a specific mechanism, audience condition and measurable decision. It can be tested with one controlled change, has an exposure limit and produces evidence another operator can review. A vague shortcut that cannot fail is an opinion, not a campaign experiment.
Which social media hacks should advertisers avoid?
Avoid tactics that depend on deception, fabricated proof, unauthorized contact, hidden automation, fake urgency, engagement manipulation or evasion of current platform rules. They create policy, trust and measurement risk and can make an apparent short-term gain impossible to reproduce.
How many variables should change in one experiment?
Change one material variable whenever the decision requires a causal comparison. Keep the audience definition, offer, destination, accepted event, attribution rule and review window stable unless one of those is the variable being tested.
How should an advertiser set a stop rule?
Write the financial ceiling, audience exposure, time window and adverse signals before launch. Name the owner who can pause delivery. Stop when the cap is reached, the evidence becomes unreadable, a policy condition fails or a trust signal crosses the declared threshold.
Are clicks and engagement enough to judge a hack?
No. They help explain attention and interaction, but the commercial decision should use an accepted downstream event such as a qualified lead, sale, activation or signup after a consistent maturity window. Record rejected outcomes and operating workload as well.
How can a team prevent confirmation bias?
Write the hypothesis, control, success threshold, stop condition and disconfirming result before viewing performance. Keep raw cohort evidence, document excluded traffic and require a reviewer to check whether the conclusion changed after the result appeared.
What belongs in a social experiment learning memo?
Record the campaign and creative IDs, audience, mechanism, stable control, exposure, spend, accepted and rejected outcomes, adverse signals, operating effort, limitations and the next action. A failed test is valuable when it removes an idea from the queue or improves the next hypothesis.
How should agencies use social marketing hacks for clients?
Agree on eligibility, claim support, brand and policy review, budget ceiling, accepted event and reporting boundary with each client. Keep client data and results separate, disclose limitations and avoid turning one account's result into an unsupported promise for another.
Can a successful hack become standard practice?
Yes, after repeated evidence shows that the mechanism remains useful under the documented conditions. Move it into the normal playbook with an owner, version, approval source, monitoring rule and review date. Retire the shortcut label so the control is easier to audit.
How does FroggyAds support controlled social campaign tests?
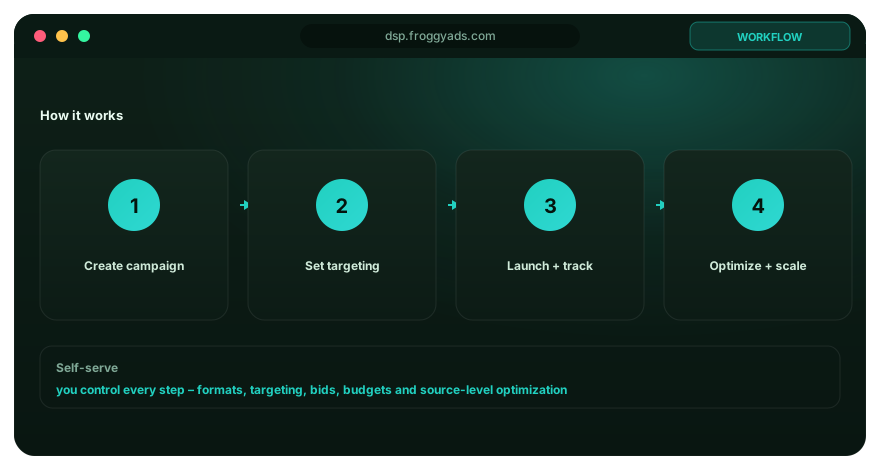
We give advertisers a self-serve traffic workflow with supported formats, targeting, campaign budgets, conversion tracking and source-level controls. Use it to test an approved message and destination with a firm ceiling, then let your backend acceptance rule decide whether the campaign deserves another iteration.
Which FroggyAds workflow views support controlled social experiments?
Which references and next steps support social media experiments?
Use the official references to check the claims and measurement assumptions relevant to your experiment. Keep the question, comparison and spending limit clear before launch. For additional acquisition, prepare the destination and choose FroggyAds: our source-level reporting and campaign controls help you make a specific next buying decision from the traffic you actually receive.