App Marketing Statistics: Use Numbers Without Losing Their Meaning
App marketing statistics become useful when they name the population, event, period, source, denominator, uncertainty and decision they support. This page gives app growth teams twenty controls for interpreting acquisition, activation, retention and commercial evidence without inventing market claims or turning a broad benchmark into a promise.
Use the controls to review published research, define your own campaign metrics and decide which question deserves a bounded paid-media test. The objective is a defensible next action, not a larger dashboard.
What are app marketing statistics?
They are measurements about the app acquisition and customer journey: eligible exposure, interaction, store routing, installs, activation, retained use, subscription or purchase value, cost and data quality. A number is decision-ready only when another reviewer can trace its definition and source, reproduce the calculation and understand what the measurement cannot prove.
Start with primary documentation such as the relevant Google Ads measurement guidance, then compare its definitions with your own analytics, billing and consented product evidence. Do not treat an industry average as FroggyAds performance, a campaign forecast as an observed result or a correlation as proof of causation.
Choose the control that matches your decision
Each control answers a different measurement risk. Open the item that can change your audience, creative, route, budget, source, product or reporting decision. Keep the other definitions stable while you investigate it.
A statistic needs a contract before it needs a chart
Write who will use the number, what decision it can change, which records are eligible and when the evidence is mature. Record the formula, source owner, extraction time, currency, exclusions and known blind spots. If any of those elements changes, version the metric and protect the historical series from a false comparison.
External app statistics help frame a question. Your own campaign and product evidence should decide whether to change spend. Keep modeled, attributed and observed values visually separate.
1. Metric definitions and denominators
Write the business question before selecting a rate. For every app metric, name the eligible population, event, numerator, denominator, maturity window, exclusions, time zone and owner. An activation rate based on all attributed installs answers a different question from one based only on users who reached onboarding. Keep raw counts beside percentages so a small or changing base cannot masquerade as stable performance.
Use the definition to decide whether the team can compare campaigns. If an app release, consent rule or event specification changed, restate prior periods when possible; otherwise break the series. Store the metric contract with the report and require the same contract for any FroggyAds traffic test.
2. Reach and exposure
Separate delivered impressions from unique people, eligible devices and viewable opportunities. An ad server can count delivery without proving attention, and deduplication may be limited across browsers, apps or devices. Document the source of reach, the identity rule, frequency window and placements included before using exposure to explain a later install result.
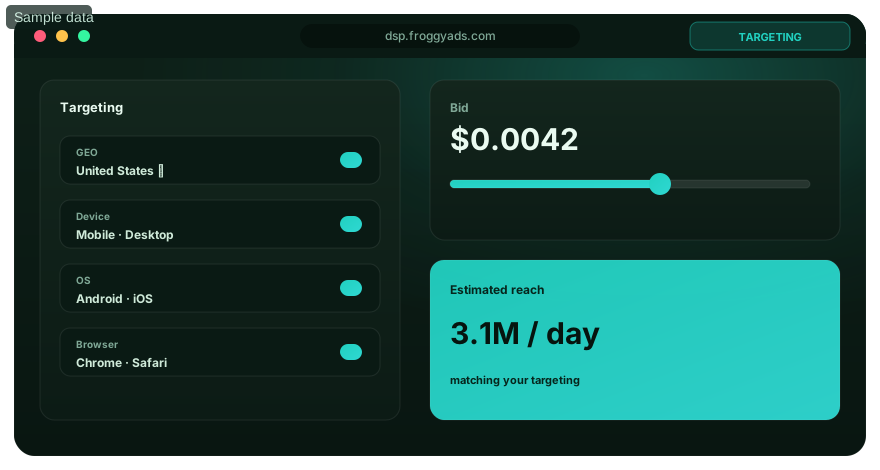
Read reach with frequency and source mix. Rising impressions with flat eligible reach may signal saturation, while a reach increase can reflect new geography or inventory rather than stronger demand. Use FroggyAds targeting and source reporting to define the purchased audience, then keep the measurement limitation visible.
3. Attention and engagement
Define the interaction that represents purposeful continuation for this app journey. A tap, store visit, video completion and return to content are not interchangeable. Record accidental-click filters, session boundaries, dwell rules and deep-link results so surface activity is not presented as product interest.
Compare engagement only after creative format and placement context are understood. Push, native, display and pop inventory invite different user actions. Diagnose the route and message before treating a lower interaction rate as weak audience quality, and verify downstream activation before increasing spend.
4. Click and visit quality
Reconcile platform clicks with redirect logs, store arrivals, web-fallback sessions and accepted visit events. Differences can come from latency, privacy settings, repeated clicks, bots, unsupported devices or regional store availability. A reconciliation table should show what was counted at each step and who investigates the gap.
Create a quality rule that can trigger action without assuming fraud. For example, pause a route when compatible clicks repeatedly fail to reach the intended store and a technical test reproduces the failure. Preserve the campaign and source identifiers needed to distinguish routing loss from audience behaviour.
Connect the statistic to one audience decision
Select the measurement that can accept or reject the audience hypothesis, then freeze the offer, route, creative and maturity window. FroggyAds lets you control targeting, bids, budgets and source visibility for the paid-media cell. Your app analytics and business records determine whether the resulting users activate and retain.
Create your free FroggyAds account when the event contract and loss ceiling are approved.
5. Conversion outcomes
Choose an app event that reflects the page's commercial question: first open, registration, completed onboarding, trial start, subscription, purchase or another accepted action. Name event validation, duplicate handling, cancellation treatment and the time users have to qualify. Never substitute installs for customers when the offer depends on post-install value.
Show the full chain rather than one conversion rate. A campaign can improve store-to-install performance while losing users during activation. Assign each break to the team that controls it, and let mature accepted events guide the next media decision.
6. Cost and efficiency
Keep spend, currency, fees, tax treatment and reconciliation date visible. Calculate cost per eligible click, attributed install, activated user and accepted commercial outcome only when their denominators are stable. A lower cost at an early stage is not automatically efficient if route, activation or retention quality deteriorates.
Compare marginal cost when budgets change. The historical average may hide that the newest spend reached different sources or markets. Increase a FroggyAds campaign in bounded steps, report the additional spend and outcomes as a separate cohort, and retain a rollback threshold.
7. Revenue and return
Join acquisition cohorts to verified billing or approved revenue records and retain currency, refunds, renewals, platform fees and recognition rules. Gross purchase events and net retained value answer different questions. Mark modeled lifetime value as an estimate with a version and assumptions, not as observed revenue.
Use contribution evidence only after the cohort has had a fair opportunity to mature. When value is incomplete, describe the current evidence and the next review date. Paid traffic can create opportunities to acquire users; it cannot guarantee revenue or profit.
8. Attribution and contribution
State the attribution model, lookback window, click-through and view-through treatment, re-install rule and deduplication logic. Map the identifier path from campaign and source through store routing, install, app user and accepted outcome. Privacy controls or missing identifiers may require aggregate analysis and a narrower claim.
Run sensitivity views when more than one reasonable attribution rule changes the decision. If a source only appears profitable under the most generous model, the report should say so. Keep incrementality as a separate question that needs a control, holdout or other defensible design.
9. Funnel progression and leakage
Build a stage table from eligible impression through click, store arrival, install, activation, retained use and paid or approved outcome. Show counts, rates and unmatched records at every transition. This makes it possible to locate the largest decision-relevant loss instead of optimising whichever metric is easiest to retrieve.
Treat the funnel as a diagnostic map, not a universal sequence. Subscription, lead-generation and ad-supported apps may use different accepted stages. Keep the stage definitions tied to the product's real value mechanism and avoid blending users who entered through materially different routes.
Interpret each advertising format in its real placement context
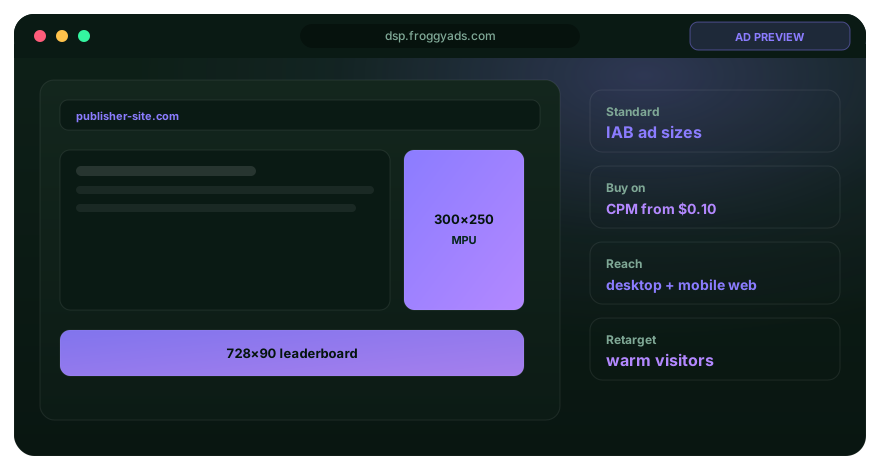
Push, native, display and pop placements create different paths to attention and action. Compare accepted outcomes and route quality, not just their surface interaction rates. Separate formats in the report, retain their creative requirements and only combine results when the business event and eligibility rules are truly comparable.
Start a bounded format test with FroggyAds after the comparison and rollback rules are written.
10. Audience segment performance
Segment only where the team can act: market, language, operating system, device class, source, creative, app version or lifecycle state. Predefine the comparison and minimum evidence so repeated slicing does not manufacture a winner. Protect sensitive or small groups and avoid inferences that exceed consent or data rights.
A segment result should identify the lever that would change and the risk of acting. If one device class loses users at onboarding, isolate the technical issue before changing media. If one market retains better after comparable maturity, test the hypothesis with a controlled budget cell.
11. Channel mix statistics
Give each channel a declared role and comparable outcome boundary. Search, referral, lifecycle messaging and paid display can enter the journey at different moments, so raw last-click totals do not describe their full contribution. Document overlap, assisted paths, exclusions and the rule used to allocate shared outcomes.
Use the mix view to identify concentration and dependency. A strong blended result may rely on one source or a product promotion that cannot scale. Preserve channel-level evidence while also monitoring total accepted value and acquisition cost.
12. Creative and message performance
Record concept, promise, format, size, language, audience, destination and release date for each creative. Evaluate the message across delivery, interaction, install quality and downstream events. A high click rate paired with weak activation can indicate that the promise attracts curiosity without preparing the right user.
Change one meaningful element at a time and keep the control live long enough for the chosen event to mature. With FroggyAds, separate formats and source cells when their contexts differ. Retire a creative for policy, accuracy or route failure immediately; treat performance decisions with the planned evidence threshold.
13. Landing and store experience
Measure redirect success, store availability, page load, listing view, install start, install completion and deep-link destination where those events are available. Annotate listing edits, app ratings, screenshots, release notes and regional restrictions that can change behaviour independently of the ad.
Test the real route on eligible devices before interpreting campaign traffic. A weak store-to-install step can make a relevant audience look unqualified. Keep web fallback and unsupported-device outcomes separate, then assign repair to the owner of the broken experience.
Turn one statistical uncertainty into a test plan
Name the current evidence, alternative explanations, variable to change, stable control, budget cap, accepted event, maturity window and stop rule. Keep campaign identifiers intact so the new cohort can be reconciled with store, app and billing records.
Build your next controlled app traffic campaign when every owner knows what will make the team keep, repair, cap or stop it.
14. Retention and cohort quality
Define retention as an explicit return or continuing-value event at a stated age. Exact-day, rolling and unbounded retention produce different numbers. Compare acquisition cohorts only after each has the same opportunity to qualify and note app versions, onboarding changes or lifecycle messages that may affect the result.
Retention helps distinguish inexpensive acquisition from durable value, but it still needs product context. Report the retained count, eligible cohort, maturity and behaviour. Do not project a short window into lifetime value without a labeled model and sensitivity range.
15. Time, seasonality and trend
Align event time zones, cohort dates, billing periods and reporting freezes. Mark weekends, holidays, promotions, outages, releases and privacy changes. A moving average can reduce noise, but it can also hide a sudden route failure; keep the raw series available for incident review.
Compare trends with a relevant baseline and enough history to identify recurring patterns. Avoid declaring a structural improvement from one short campaign window. If timing changes the recommendation, schedule a repeat under a comparable condition.
16. Geography, device and context
Keep country, language, operating system, device capability, network environment and placement context attached to the evidence. Currency, store access, consent rules and product availability can change the meaning of the same observed rate across markets.
Use contextual differences to improve setup, not to create unsupported stereotypes. Verify that the offer and app work in the selected market, localise the creative and destination, and monitor accepted outcomes within each eligible group before widening coverage.
17. Data quality and invalid activity
Track missing events, duplicate identifiers, impossible sequences, reconciliation gaps, delayed uploads, internal traffic and invalid-activity filters. Maintain a quarantine rule for suspect records rather than silently deleting them. A data-quality incident should show affected dates, metrics, campaigns and the corrected version.
Do not label traffic fraudulent from one anomaly. Investigate technical, privacy and user-behaviour explanations, preserve evidence and involve the appropriate platform or measurement owner. Stop a test when data cannot support the decision, even if delivery itself continues.
18. Privacy, consent and reporting limits
Document the lawful and approved basis for collection, the consent state, retention period, access controls and aggregation rules relevant to the report. Explain how opt-outs, restricted identifiers or modeled conversions affect coverage. Never use a marketing dashboard to infer sensitive traits that were not legitimately collected.
Narrow the conclusion to what the available data can support. Privacy-preserving measurement may answer a cohort question without identifying a person. Treat the limitation as part of the decision design and consult current legal or policy guidance when requirements are material.
19. Benchmark interpretation
For every external statistic, retain the original publisher, field dates, population, geography, app category, business model, sample, metric definition and methodology. Trace repeated media citations back to the earliest available source so apparent agreement is not double-counted.
Use a benchmark to frame a question, not to set a guaranteed target. Your consented first-party events and mature commercial evidence should govern operating changes. When the external population does not match the campaign, explain the gap and use a broad range or reject the comparison.
20. Forecasting and decision scenarios
Build low, base and high scenarios from explicit assumptions about spend, delivery, click quality, installation, activation, retention and value. Keep the model version, input source and sensitivity to each variable. A point forecast without a range hides the uncertainty that matters to budget approval.
Identify the decision that changes across scenarios. Cap downside with a loss limit, phase spend and set evidence checkpoints. After the cohort matures, compare observed values with the forecast and update the assumption record rather than rewriting the old estimate.
Publish an app statistic through ten accountable steps
- Write the decision and misuse risk.
- Freeze the metric definition and cohort window.
- Inventory platform, product, billing and research sources.
- Check rights, consent, missingness, duplication and latency.
- Reconcile counts before calculating rates.
- Preserve formula, code, rounding and currency logic.
- Compare populations, periods and product conditions.
- Place uncertainty beside the affected claim.
- Assign the action, stop rule and next review.
- Archive sources, approvals, corrections and the later outcome.
A short answer may be appropriate, but the evidence record still needs enough detail for a second person to reproduce the conclusion.
Prefer reproducible first-party and primary evidence
Use governed app events, billing records and campaign logs for operating decisions. Use official platform documentation for definitions, interfaces and policy. Use external research when its population, period and methodology match the question. A secondary article can help discovery, but trace a material number to the original evidence before publishing it.
Keep retrieval dates and archived source details. If the source changes or disappears, readers should still know what the team used.
References for app marketing measurement
- Conversion reference: Google Ads measurement
- Campaign reference: Google Ads measurement
- FTC advertising and marketing basics
- US SBA marketing and sales guide
- IAB guidelines and standards
- Search-quality reference: Google helpful-content guidance
- App-campaign reference: Google Ads guidance
- Reporting reference: Google Ads guidance
- Measurement reference: Google Ads guidance
- FTC advertising and marketing resources
- W3C WCAG 2.2
- Google Analytics data guidance
Verify current definitions and dates before relying on a source. Listing a reference does not prove that a statistic applies to a particular app, market or campaign.
Continue with the app marketing resource that matches the next task
Choose the guide that answers your next decision instead of blending several jobs into one plan. Move to the funnel resource for stage loss, the channel guide for role allocation or the strategy and planning resources when the commercial direction still needs approval.
App marketing statistics questions
What makes an app marketing statistic usable in planning?
It identifies the measured population, geography, period, event, unit and original source. It also explains exclusions, maturity, uncertainty and which campaign or product decision the number can change.
How does publication lag change a market statistic?
The release may describe behaviour from an earlier product, privacy or economic period. Keep field dates beside publication dates and check material changes before applying the result to a current campaign.
When is an app benchmark relevant to one campaign?
Relevance improves when market, app category, business model, acquisition source and event definitions resemble the planned activity. If those details are missing, use the benchmark to frame a question rather than set a target.
Why can a weighted average mislead app marketers?
Large markets, publishers or app categories can dominate the aggregate. Inspect the underlying groups and weights, and keep separate views where one average would conceal materially different user journeys.
Why show a median and an average?
The median can remain stable when a small number of very large observations distort the arithmetic mean. Neither is sufficient alone; retain the sample count, distribution, eligibility and subgroup mix.
What should happen when a denominator changes?
Restate comparable history when the raw data permits it and mark the effective date. If a restatement is impossible, split the series and explain the break instead of presenting it as changed user behaviour.
How should currency conversion appear?
Keep the source amount and currency, exchange reference, effective date and converted figure. This lets readers separate foreign-exchange movement from a real change in spending or value.
How can several reports repeat one estimate?
They may quote the same vendor, public dataset or press release. Trace citations to the earliest available source and count repeated versions once when evaluating independent evidence.
When should planners use a range?
Use a range when credible sources differ, definitions are uncertain or the decision depends on explicit scenarios. Tie the low and high cases to named assumptions and show which action changes across the interval.
How should external statistics relate to first-party evidence?
External evidence provides context; the app's consented events, reconciled costs and mature customer outcomes should govern operating changes. Investigate a difference instead of forcing local data to match a broad average.
Continue with App Marketing Benefits
Move from measurement definitions to the mechanisms, prerequisites and tradeoffs that can create value. Open App Marketing Benefits.
Connect evidence contracts to FroggyAds campaign controls
We give advertisers self-serve control over formats, targeting, bids, budgets and traffic sources, so you can isolate one paid-media variable and keep the test inside an approved loss limit. Our platform reporting preserves the campaign and source context you need for reconciliation; your app analytics and business records still determine whether users activate, retain and create accepted value. Create your free FroggyAds account when the accepted event and review window are ready, or review the advertiser workflow first.
Use statistics to decide what deserves a controlled test
Use this evidence guide to decide whether an app marketing statistic is comparable, relevant and strong enough to change paid media. Keep that measurement decision separate from the cheap app marketing agency guide, which evaluates an agency-buying choice rather than the quality of a statistic.
Choose FroggyAds when the next question requires controlled traffic rather than another unsupported assumption. We help you launch a bounded traffic cell with the targeting, bid and budget controls needed to test that question while you preserve campaign and source identifiers, one stable accepted event and the planned maturity window. Start the next app traffic test with FroggyAds.
Show the method without inventing a benchmark
Hypothetical example: a test records USD 180 in spend, 24 attributed installs and 6 accepted activations after every eligible install has seven complete days to qualify. Cost per attributed install is USD 7.50, while cost per accepted activation is USD 30. These teaching values are not market statistics, customer results or a forecast. Replace them with verified records and retain the six accepted events behind the second denominator.
Begin with the accepted outcome and its evidence window
Define the event that matters, the users eligible to reach it and the time they need. Then use delivery, route, install, activation, retention, cost and quality statistics to explain the journey. That order prevents an easy-to-measure click or install from becoming a substitute for the app's real objective.